HubSpot
HubSpot Data: Structure, Quality & Growth Strategy
· 15 min read
Your HubSpot portal contains thousands of contact records, hundreds of deals, and countless activities logged every day. Yet when leadership asks for a clean revenue forecast or your sales team needs reliable customer insights, the data tells conflicting stories. This disconnect between data volume and data value defines the central challenge facing growing businesses in 2026. Understanding how to properly structure, maintain, and leverage hubspot data transforms your CRM from a contact database into a strategic revenue engine.
Understanding the HubSpot Data Model
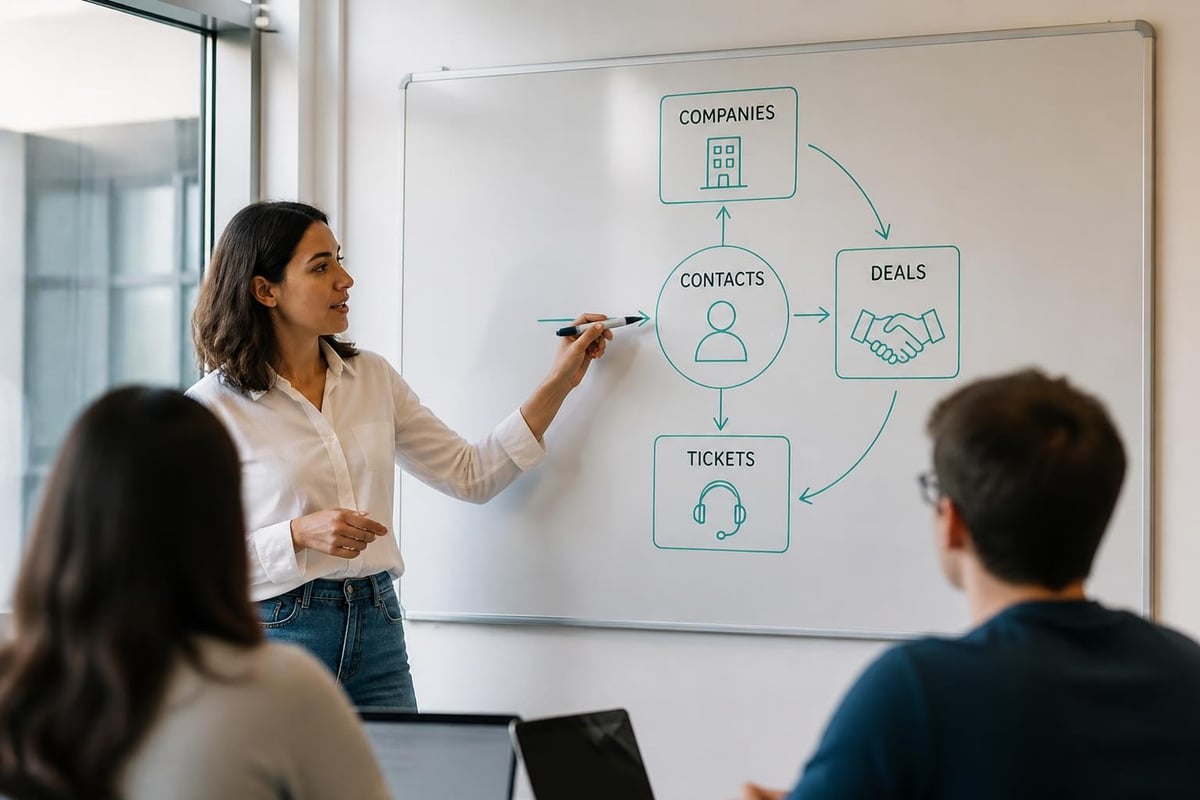
HubSpot organizes information through a relational database structure built around core objects: Contacts, Companies, Deals, Tickets, and custom objects. Each object stores specific attributes as properties, and associations create relationships between different records. This architecture enables powerful segmentation and reporting, but only when implemented correctly.
Standard Objects and Their Purpose
The platform provides four standard CRM objects out of the box, each serving distinct business functions. Contacts represent individual people, storing communication preferences, lifecycle stages, and engagement history. Companies aggregate firmographic data, tracking account-level information like industry, employee count, and annual revenue. Deals represent sales opportunities, moving through pipeline stages with associated revenue values and close dates. Tickets manage service requests and support interactions, creating a closed-loop between sales promises and service delivery.
Understanding how these objects relate to each other prevents the most common hubspot data quality issues. A single contact might be associated with multiple companies if they change jobs or wear multiple hats. Deals should always link to both a company and at least one contact decision-maker. Breaking these fundamental relationships creates orphaned records that skew reports and confuse sales teams.
Custom Objects for Business-Specific Needs
When standard objects cannot adequately represent your business model, custom objects extend HubSpot's data architecture to match your unique processes. A manufacturing business might create a "Production Run" object to track orders through fulfillment. A professional services firm could build a "Project" object that links to deals, contacts, and recurring revenue streams.
The decision to create custom objects should never be taken lightly. Each new object adds complexity to your data model, requires ongoing maintenance, and impacts reporting architecture. Before building custom objects, exhaustively explore whether native objects with custom properties can accomplish the same goal. Many teams create unnecessary custom objects because they did not properly understand property types and association labels.
Decision Factor | Use Standard Object + Custom Properties | Build Custom Object |
|---|---|---|
Data cardinality | One-to-one or simple one-to-many | Complex many-to-many relationships |
Lifecycle needs | Follows standard buyer journey | Unique lifecycle stages required |
Reporting requirements | Standard sales/marketing reports sufficient | Need object-specific dashboards |
Integration complexity | Supported by native connectors | Requires custom API work |
Maintaining Data Quality at Scale
Poor hubspot data quality costs businesses more than just inaccurate reports. Sales reps waste hours chasing dead-end leads because demographic data is outdated. Marketing campaigns underperform when segmentation relies on incomplete or inconsistent field values. Revenue forecasts mislead leadership when deal stages do not reflect actual pipeline health.
Common Data Quality Challenges
Duplicate records represent the most visible symptom of data decay. They emerge when multiple team members create contacts for the same person, when form submissions bypass deduplication rules, or when integrations import records without proper matching logic. HubSpot's native duplicate management tools help, but they cannot catch every scenario, especially across objects or when data comes from multiple sources.
Incomplete records undermine every downstream process that depends on that data. A contact missing an email address cannot receive nurture campaigns. A company without an assigned owner falls through pipeline cracks. A deal lacking a close date skews forecasting. Requiring critical fields at the point of data entry prevents gaps, but legacy data and integration feeds often introduce incomplete records that require systematic cleanup.
Inconsistent formatting makes segmentation nearly impossible. One rep enters phone numbers as (555) 123-4567 while another uses 555-123-4567 or 5551234567. Job titles vary between "VP of Sales," "Vice President, Sales," and "Sales VP." Without standardization, filters meant to target specific segments miss large portions of your database. Data quality initiatives establish the formatting standards and validation rules that prevent these inconsistencies.
Implementing Data Governance
Governance transforms data quality from a one-time cleanup project into a sustainable practice. Start by documenting your data dictionary: which properties exist, what values they accept, who can edit them, and how they drive business processes. This documentation becomes the single source of truth that keeps teams aligned as your hubspot data model evolves.
Validation rules enforce quality at the point of entry. Configure required fields for critical properties. Set up property validation to ensure email addresses follow proper formatting and phone numbers match expected patterns. Use dependent fields to automatically populate related values based on previous selections. These technical controls prevent bad data from entering your system in the first place.
Regular audits catch quality issues before they compound. Monthly reviews should identify duplicate records, flag incomplete profiles, and surface formatting inconsistencies. Assign clear ownership for each audit area. Marketing owns contact data completeness. Sales manages deal pipeline accuracy. Operations maintains company hierarchy and parent-child relationships.
Organizations that treat data quality as an ongoing discipline rather than a periodic project report significantly higher CRM adoption rates and forecast accuracy. The investment in governance processes pays dividends across every team that depends on reliable hubspot data.
Architecting for Reporting and Analytics
The ultimate value of your CRM data emerges when it drives business decisions. Revenue leaders need accurate pipeline forecasts. Marketing teams require attribution reporting that connects campaigns to closed revenue. Service managers want trend analysis on ticket volume and resolution time. Building this reporting layer requires intentional architecture from day one.
Property Strategy for Reporting
Every property you create should serve a specific reporting or automation purpose. Calculated properties derive values from other fields, ensuring consistency and reducing manual data entry. Pipeline velocity calculations, for example, automatically compute how long deals spend in each stage based on stage entry timestamps.
Score properties consolidate complex criteria into single numeric values that drive prioritization. Lead scoring combines demographic fit, engagement level, and buying signals into one number that sales teams use to prioritize outreach. Customer health scores aggregate product usage, support ticket volume, and renewal risk factors to identify accounts needing attention.
Single-line text: Names, job titles, short identifiers (limit use in reporting)
Multi-line text: Notes, descriptions, comments (not reportable)
Dropdown select: Standardized categories (ideal for segmentation and filtering)
Number: Quantitative values, revenue figures, counts (enables calculations)
Date picker: Timestamps, milestones, renewal dates (powers time-based reporting)
Checkbox: Binary yes/no flags (simple filtering and workflow triggers)
Choosing the correct property type directly impacts reporting capabilities. A job title stored as single-line text allows fuzzy matching but complicates grouping. The same field as a dropdown with standardized values enables clean segmentation. Revenue stored as text cannot be summed. Understanding these limitations before creating properties prevents costly rebuilds later.

Building Scalable Dashboards
Effective dashboards answer specific business questions for defined audiences. Sales managers need different views than individual contributors. Marketing leadership cares about different metrics than campaign managers. Attempting to build one dashboard that serves everyone results in cluttered, unused reports.
Start with the question you need to answer, then work backward to identify the required data points. "Which marketing campaigns generate the highest-value opportunities?" requires campaign data, deal value, close rates, and source attribution. "How long do deals typically spend in each pipeline stage?" needs deal creation date, stage history, and close date. Missing any component in your hubspot data architecture makes the question unanswerable.
Report types in HubSpot each serve specific analytical needs:
Report Type | Best For | Limitations |
|---|---|---|
Single object | Contact lists, deal pipelines, ticket volume | Cannot combine data across objects |
Cross-object | Attribution, lifecycle analysis, account rollups | Limited to two objects without custom reports |
Custom report builder | Complex multi-object analysis, calculated metrics | Requires Professional or Enterprise tier |
Analytics tools | Funnel analysis, revenue attribution, ROI tracking | Data source and object restrictions apply |
Teams that outgrow native reporting capabilities often export hubspot data to external business intelligence platforms. HubSpot's Data Sync functionality enables real-time connections with data warehouses, while ETL platforms like Fivetran provide automated pipelines that keep external systems current. For enterprises needing advanced analytics, BigQuery's HubSpot connector facilitates large-scale data analysis alongside other business systems.
Integrating HubSpot Data Across Your Tech Stack
No business runs on HubSpot alone. Your CRM needs to exchange data with marketing automation platforms, accounting systems, customer success tools, and operational databases. Integration architecture determines whether these systems work together seamlessly or create conflicting data silos.
Native Integrations vs. Custom Solutions
HubSpot's App Marketplace offers hundreds of pre-built integrations with popular business tools. These native connectors handle authentication, field mapping, and sync frequency out of the box. They work well for standard use cases but often lack flexibility for complex data transformations or bidirectional sync requirements.
Middleware platforms like Zapier bridge gaps between applications without custom development. They excel at simple trigger-action workflows: when a deal closes in HubSpot, create an invoice in QuickBooks. When a support ticket is created, notify the team in Slack. However, middleware solutions struggle with complex data transformations, high-volume operations, or scenarios requiring real-time synchronization.
For businesses with unique requirements, custom API integrations provide complete control over data flow. Custom development enables sophisticated mapping logic, handles edge cases that break pre-built connectors, and implements business rules that generic integrations cannot support. Teams managing ongoing hubspot data integrations find that having experts who can build and maintain custom connections saves significant time compared to wrestling with limitations of off-the-shelf tools.
Data Hygiene in Integration Scenarios
Integrations amplify existing data quality problems. A contact with an invalid email address in HubSpot will create a bad record in your email platform. Duplicate deals sync to your accounting system and create billing confusion. Missing required fields cause integration failures that require manual intervention.
Pre-sync validation prevents bad data from propagating. Set up workflows that check data completeness before records sync to external systems. Flag contacts missing required fields so they can be enriched before they export. Establish quality thresholds that integration jobs must meet before executing.
Sync monitoring catches failures and inconsistencies before they impact business operations. Track integration success rates daily. Alert responsible teams when sync jobs fail or when error rates exceed acceptable thresholds. Document common failure patterns and create runbooks that help teams resolve issues quickly.
Teams often discover during integration projects that their hubspot data model needs refinement. Fields that seemed adequate in isolation reveal limitations when mapped to external systems. Lifecycle stages that work for internal processes do not align with external platform requirements. Addressing these architectural gaps requires strategic planning and expert implementation to avoid creating technical debt.
Preparing HubSpot Data for AI and Advanced Analytics
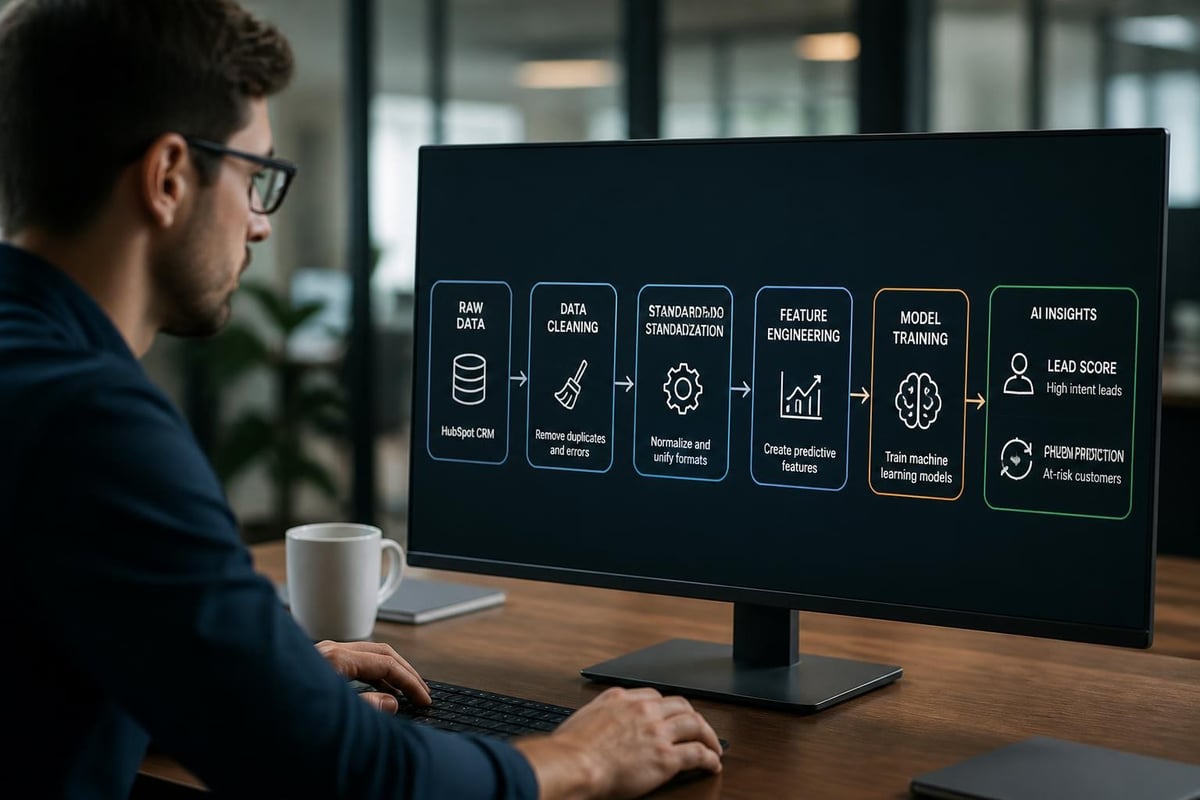
Artificial intelligence transforms how businesses extract insights from CRM data, but AI models require high-quality, well-structured inputs to generate reliable outputs. Preparing hubspot data for AI initiatives involves cleaning historical records, standardizing formats, and architecting data models that support machine learning workflows.
Data Requirements for AI Success
Machine learning algorithms identify patterns in historical data to predict future outcomes. Lead scoring models analyze which contact attributes and engagement behaviors correlate with closed revenue. Churn prediction examines customer health signals, product usage, and support interactions to flag at-risk accounts. Revenue forecasting uses deal characteristics, historical close rates, and seasonal trends to project future pipeline performance.
These models only work when training data accurately represents reality. Preparing CRM data for AI requires cleaning historical records, handling missing values, and normalizing data distributions. A lead scoring model trained on incomplete contact records will miss important patterns. A churn model that includes incorrectly categorized customer health scores produces unreliable predictions.
Feature engineering transforms raw hubspot data into signals that machine learning models can interpret. Rather than feeding an AI model raw deal stage names, calculate metrics like "average days in stage" or "stage progression velocity." Instead of using unstructured text from call notes, extract sentiment scores or topic classifications. These engineered features provide clearer signals that improve model accuracy.
Implementing AI-Powered Workflows
Once your data foundation is solid, AI tools can automate repetitive processes and surface insights that humans miss. Predictive lead scoring automatically prioritizes prospects based on their likelihood to convert, enabling sales teams to focus energy on high-probability opportunities. Sentiment analysis on support tickets routes frustrated customers to senior agents before situations escalate. Content recommendations suggest relevant resources based on prospect engagement patterns and journey stage.
HubSpot's native AI capabilities, including Breeze AI features, provide accessible entry points for teams new to AI implementation. These tools leverage your existing hubspot data without requiring data science expertise. For more sophisticated use cases, AI implementation specialists can deploy custom models and integrate third-party AI platforms that extend HubSpot's capabilities.
The key to successful AI adoption lies in starting with well-defined business problems and clean data foundations. Teams that chase AI for its own sake waste resources building models that solve non-problems or produce insights nobody acts on. Organizations that approach AI strategically achieve measurable improvements in conversion rates, customer retention, and operational efficiency.
Scaling Your Data Architecture
As businesses grow, hubspot data volume increases exponentially. A startup with 5,000 contacts and 200 deals faces different challenges than an enterprise managing 500,000 contacts, 50,000 deals, and complex parent-child company hierarchies. Scalable architecture anticipates these growth patterns and implements structures that perform well at increasing data volumes.
Performance Considerations
Large datasets impact every aspect of HubSpot performance. List loading times slow when segments contain tens of thousands of records. Workflow execution delays when processing rules evaluate against massive datasets. Report generation times out when aggregating data across hundreds of thousands of records and multiple objects.
Optimization strategies address these performance bottlenecks:
Property usage: Minimize the number of properties created. Every property adds overhead to record loading and database queries.
Active list criteria: Complex list logic with multiple OR conditions performs poorly. Simplify segmentation rules where possible.
Workflow triggers: Enrolling all contacts in workflows creates unnecessary processing load. Use specific enrollment criteria to limit volume.
Report date ranges: Shorter date ranges reduce the data volume reports must aggregate. Archive historical data when long-term trends are not needed.
API call efficiency: Batch operations rather than individual record updates when working with HubSpot's API programmatically.
Teams managing large-scale hubspot data operations benefit from ongoing optimization support that identifies performance issues before they impact daily operations. Regular portal audits catch growing technical debt, unused workflows consuming resources, and architectural patterns that will cause problems as data volume grows.
Data Retention and Archiving
Not all data deserves permanent residence in your active CRM. Inactive contacts who have not engaged in years clutter segmentation and slow list building. Closed-lost deals from five years ago provide minimal value for current forecasting. Resolved tickets beyond warranty periods rarely need immediate access.
Implementing data retention policies balances regulatory requirements, operational needs, and system performance. Define clear criteria for when records move from active to archived status. Document what happens to archived data: does it export to long-term storage, does it remain queryable for compliance, or does it delete permanently after a retention period?
Before archiving hubspot data, verify that historical reporting needs are met. Revenue trend analysis might require five years of closed deal data. Customer lifetime value calculations depend on complete purchase history. Legal or compliance requirements may mandate minimum retention periods for specific record types. Building robust reporting architecture often includes extracting historical data to external warehouses before removing it from active HubSpot environments.
Operationalizing Revenue Data
The most valuable hubspot data directly connects to revenue generation and business growth. Sales pipeline health, marketing attribution, customer expansion, and renewal forecasting all depend on accurate, timely CRM data. Operationalizing this data means embedding it into daily workflows where it drives decisions and actions.
Pipeline Visibility and Forecasting
Revenue leaders need real-time visibility into pipeline health across multiple dimensions. Stage distribution shows whether enough opportunities exist in early stages to meet future targets. Deal velocity tracks how quickly opportunities progress toward close. Win rate analysis by source, rep, or product reveals which activities generate the highest-quality pipeline.
Accurate forecasting requires disciplined pipeline management. Sales teams must update deal stages promptly to reflect true opportunity status. Close dates need realistic assessment, not optimistic guesses. Deal amounts should represent qualified, validated figures rather than aspirational values. When teams treat hubspot data updates as administrative overhead rather than strategic discipline, forecast accuracy suffers and leadership loses confidence in projections.
Attribution and ROI Measurement
Marketing teams constantly face pressure to demonstrate ROI. Which campaigns drive pipeline? What content converts prospects? How do different channels contribute to revenue? Multi-touch attribution models distribute credit across the various touchpoints that influence buying decisions, providing clearer pictures of marketing impact than simple first-touch or last-touch attribution.
Building attribution models requires clean source data throughout the customer journey. Every form submission needs accurate source tracking. Campaign membership must be properly assigned. Lifecycle stage progressions need timestamp accuracy. Without this foundational hubspot data quality, attribution models produce misleading insights that drive poor investment decisions.
Organizations implementing comprehensive RevOps strategies align their entire revenue team around shared data definitions and unified reporting. When marketing, sales, and customer success all work from the same hubspot data foundation, revenue operations become predictable, scalable, and optimized for growth.
Managing hubspot data effectively separates growing businesses from those struggling to scale. Clean data structures, consistent quality standards, and strategic architecture transform your CRM from a contact database into a revenue engine that powers decision-making across your organization. Whether you are refining an existing HubSpot implementation or building a new system from the ground up, the expertise to architect scalable data models and maintain them over time is essential. Revio specializes in helping businesses optimize their HubSpot data architecture, implement quality controls, and build the reporting infrastructure that drives sustainable growth.
One clear next move
Build the system your team needs to grow.
Tell us which tools you use, where work is breaking and what growth is asking the team to do next. We will show you the right platform, system design and level of ongoing support.
Choose the toolsConfirm the platforms and licenses your teams actually need.
Build the systemDesign the process, data, automation, integrations and reporting around the work.
Keep it growingDecide what Revio should manage after launch.